Baidu has launched Apollo World, an artificial-intelligence simulation system designed to create changing road environments for autonomous-driving development. The company says the system can generate up to 100,000 kilometers of simulated driving data a day, including real-time camera and lidar sensor streams, and that it is already being used to train its Apollo Go robotaxi service. [1]
The significance is less about the arrival of another driving simulator than about where the autonomous-vehicle bottleneck may be moving. Robotaxi developers can accumulate large volumes of ordinary driving data on public roads, but rare and safety-critical situations are expensive, slow and sometimes unacceptable to reproduce in the real world. A system capable of producing high-throughput synthetic sensor data could make it faster to train and test vehicles against those edge cases—although simulated kilometers are not equivalent to independently verified safe miles on public roads.
By the numbers
- 100,000 km per day: Baidu’s stated maximum daily output of simulated driving data.
- 2 sensor modalities: Apollo World generates real-time camera and lidar streams.
- November 3: Date of Baidu’s Apollo World launch announcement.
- Apollo Go: Baidu says the robotaxi operation is already using the system for training.
Why synthetic edge cases matter more than routine miles
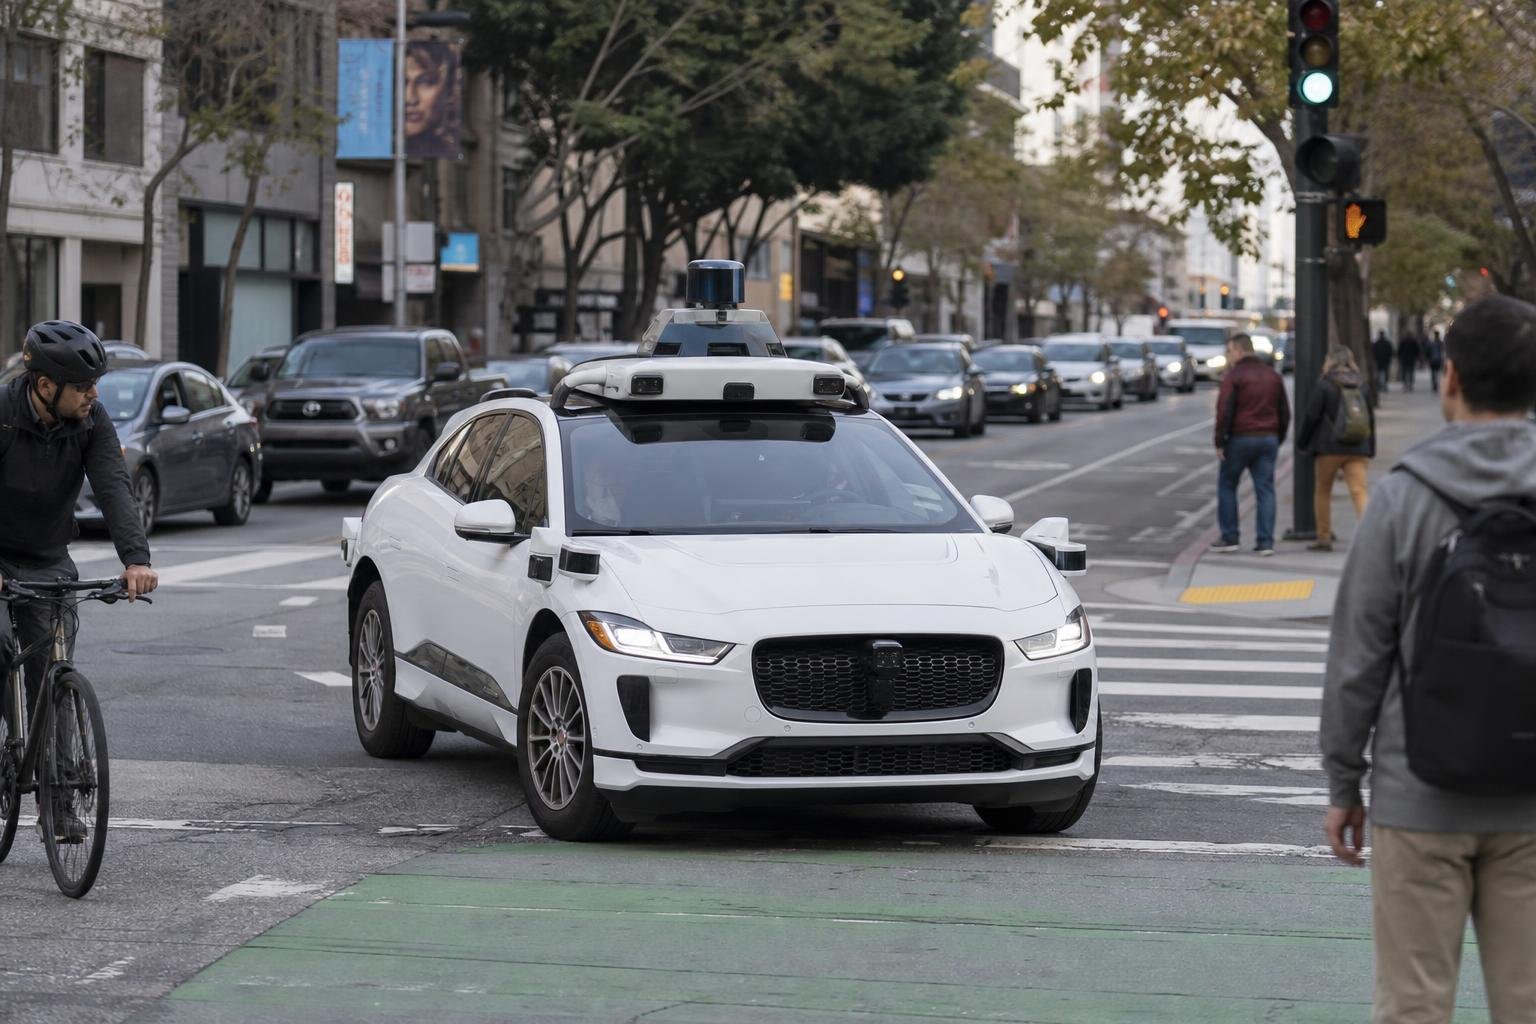
Autonomous-driving systems need exposure to a far wider range of conditions than a vehicle will encounter during normal urban operation. The difficult cases include an obstructed pedestrian emerging from behind a parked vehicle, a cyclist making an unexpected maneuver, conflicting hand signals from traffic officers, temporary construction patterns, sensor degradation in bad weather, and unusual interactions among multiple road users.
Real-world fleets remain essential because they capture the complexity of actual streets: imperfect road markings, local driving behavior, vehicle occlusion, changing light and sensor noise. But collecting sufficient examples of rare events through road testing can require long operating periods, broad geographic coverage and substantial fleet expense. Some scenarios are also too hazardous to stage repeatedly with real vehicles.
That creates a data-distribution problem. A fleet may log many hours of uneventful travel, yet see relatively few examples of the events that place the greatest demands on perception, prediction and planning software. Simulation is intended to change that balance. Rather than wait for an edge case to occur naturally, engineers can create variants of the case, alter traffic density or lighting, move the point of occlusion, change sensor perspective, and test whether a revised software stack behaves consistently.
Apollo World’s claimed output suggests Baidu is treating synthetic-data generation as an industrial-scale development input. The strategic question is not whether 100,000 simulated kilometers can replace 100,000 physical kilometers. It cannot. The question is whether those simulated kilometers can be targeted at the failures and coverage gaps that make additional real-world testing most valuable.
What Apollo World appears to add
According to Baidu, Apollo World simulates evolving road environments and produces real-time camera and lidar data. [1] That sensor-level output is important. Modern automated-driving stacks do not simply consume a list of object positions; they commonly rely on raw or near-raw sensor information to detect, classify and track road users, estimate scene geometry, and build a representation of the vehicle’s surroundings.
Camera simulation must model visual details that affect perception, including illumination, shadows, glare, weather, motion blur, occlusion and object appearance. Lidar simulation must model scene geometry, range, reflectivity, point density and sensor noise. For a simulated scene to be useful in training, the camera and lidar streams must also remain coherent with one another over time. A vehicle, pedestrian or bicycle cannot appear in one sensor stream but be geometrically inconsistent in another.
The reference to evolving road environments also points to a key simulation requirement: temporal consistency. Autonomous vehicles make decisions over sequences, not isolated images. A useful scenario must preserve credible movement, changing visibility, traffic interactions and consequences of the vehicle’s own actions. If a simulator can alter these variables while maintaining physically plausible sensor outputs, it can produce many closely related tests from a single real-world pattern.
For training, such a system can generate labeled examples at scale. For validation, it can repeatedly execute defined scenarios against a candidate software release. The second use is particularly important: a developer can compare software versions against the same scenario library and identify whether a change fixes one issue while creating a regression elsewhere.
Training faster is not the same as proving safety
Baidu’s claim describes simulated-data throughput, not a measured safety outcome. Distance in simulation is an operational metric for computing and scenario generation; it is not a direct equivalent of distance driven by paying passengers on public roads. A simulated kilometer has value only to the extent that the environment, sensor behavior, actors and evaluation criteria represent risks that matter outside the simulator.
This is the central challenge known broadly as the simulation-to-reality gap. A model trained on synthetic data can learn patterns that are highly useful in the simulated environment but fail when exposed to unexpected materials, unusual road geometry, local behavior, sensor artifacts or weather effects that the generator did not represent accurately. More simulated data does not necessarily solve this problem if the data has systematic blind spots.
Validation also requires more than demonstrating that a vehicle completes a scenario. A credible safety process needs clear scenario definitions, pass-and-fail thresholds, tests for near misses and rule violations, and evidence that the scenario set covers relevant operational risks. Developers must test adverse outcomes as well as nominal behavior: late detections, false positives, uncertain object classification, degraded sensors and compound failures involving multiple agents.
Independent evidence will therefore matter more than headline simulation volume. Useful indicators would include whether Apollo World improves the rate at which Baidu finds and resolves safety-critical failures, how it is calibrated against real sensor logs, how developers measure coverage, and whether the system’s results correlate with performance in real Apollo Go operations. The Reuters report says Apollo World is already used to train Apollo Go, but it does not establish a separate, independently audited safety comparison. [1]
Implications for Baidu and the robotaxi market
For Baidu, Apollo World could reduce the cost and elapsed time associated with iterative model development. Once a simulator and scenario-generation pipeline are established, engineers can run large test matrices without putting more vehicles, safety personnel or test operations on the road. That can shorten the feedback loop between a detected issue, a software change and a repeatable evaluation.
The potential advantage is especially strong in urban robotaxi deployment, where each city can introduce different traffic conventions, road layouts, weather patterns and construction practices. Synthetic generation may help a developer adapt a system to a new operating domain before collecting a full volume of local real-world data. Real-world collection remains necessary, but it can become more targeted: data from the street is used to discover gaps and calibrate the simulator, while the simulator expands those findings into a larger training and testing set.
Across the industry, that dynamic could shift competition away from headline fleet mileage alone. Operational fleets still provide a difficult-to-replicate source of real sensor data and passenger-service experience. Yet companies with better scenario generation, simulation fidelity, labeling infrastructure and automated regression testing may be able to convert real-world observations into software improvements more efficiently than rivals that rely primarily on additional road miles.
The commercial impact will depend on integration. A high-throughput generator is valuable only if its output feeds reliably into data curation, model training, closed-loop testing and release decisions. The harder competitive asset is not merely a simulator, but a workflow that can identify a real-world failure, reproduce it faithfully, generate meaningful variations, improve the model and verify the result before deployment.
What to watch next
The next evidence to look for is specificity. Baidu will need to show how Apollo World selects scenarios, whether it can generate rare multi-agent interactions rather than visual variations alone, and how closely its sensor streams match observations from physical vehicles. It will also be important to distinguish the system’s roles in training, offline testing and formal safety validation; those are related tasks, but they demand different levels of fidelity and assurance.
Regulators, city partners and riders are unlikely to treat simulated distance as a substitute for transparent evidence from deployed service. But simulation can still change the economics of building safer autonomous systems. If it helps engineers discover failure modes earlier and reserve public-road testing for the cases that most need real-world confirmation, it can make robotaxi development more disciplined as well as faster.
Editor’s Take
I see Apollo World as a potentially important engineering investment because the scarce resource in autonomous driving is not simply road time. It is high-quality feedback on the strange, consequential cases that fleets rarely encounter and teams need to solve before scaling service. A simulator that can turn one difficult observation into thousands of controlled, sensor-consistent variants can materially improve development velocity.
But I would not treat the 100,000-kilometer figure as a safety metric. The practical proof will be whether Baidu can show that synthetic scenarios predict real failures, improve Apollo Go’s behavior in those cases and make releases more measurable. The companies that win this phase will be those that build the tightest loop between real streets and simulation—not those that report the largest virtual odometer.