Nvidia has participated in a $14 million Series B financing for Simplismart, a Bengaluru-based startup building software intended to make AI model deployment and serving more efficient across GPU and cloud infrastructure. The company says its platform cut GPU serving costs by 56% for one customer and that its annualized revenue run rate increased 14-fold in the six months before the announcement.[1]
The investment highlights a consequential shift in AI infrastructure. The industry’s capacity problem is no longer defined solely by who can procure the most accelerators. For companies already operating GPU fleets, the next source of economic advantage is increasingly the software that decides which model runs where, at what precision, in what batch size, and on which hardware. Those choices can determine whether expensive GPUs sit underutilized or deliver substantially more inference work per dollar.
By the numbers
- $14 million: Simplismart’s Series B financing.
- 56%: Reported reduction in GPU serving costs for one Simplismart customer; this is a company-reported result, not an industry benchmark.
- 14-fold: Growth in Simplismart’s annualized revenue run rate over six months, according to the company.
- Bengaluru: Simplismart’s home base, placing the company in one of India’s largest software and AI engineering centers.
What Simplismart is selling: operational efficiency, not new chips
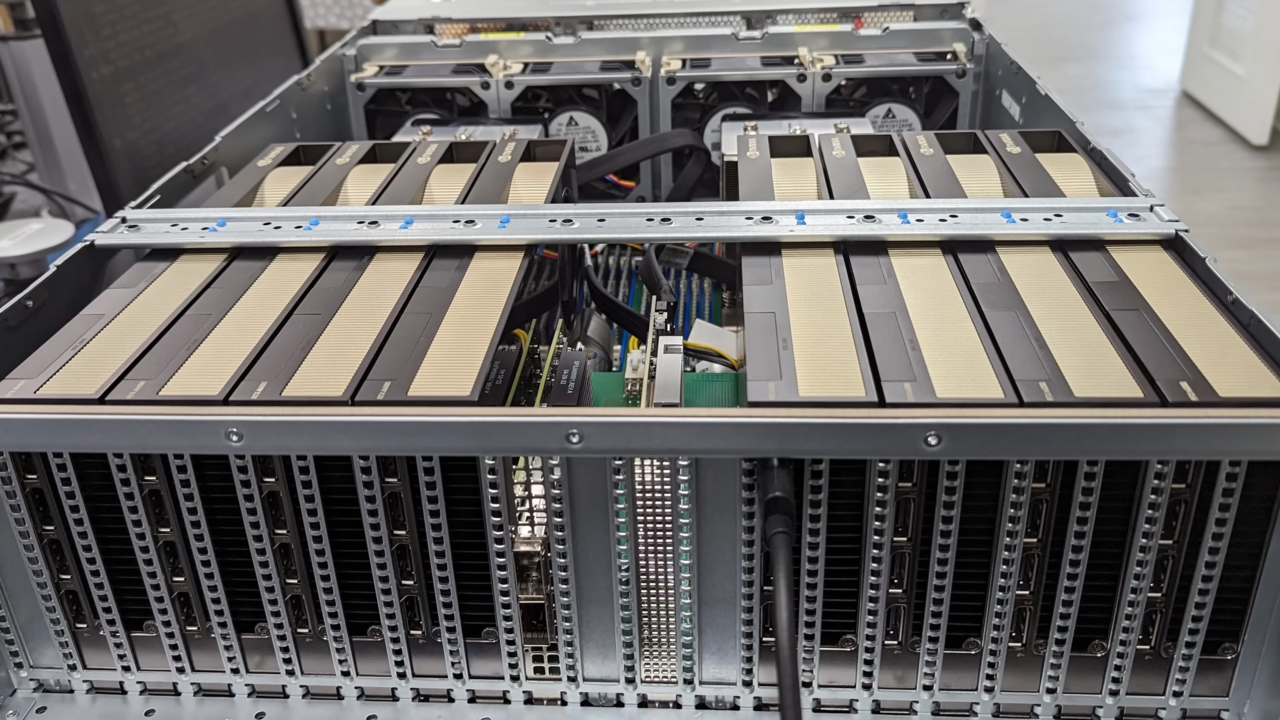
Simplismart operates in the software layer between an organization’s AI applications and the GPU and cloud resources that execute them. Its purpose is not to train foundation models or manufacture accelerators. It is to help enterprises deploy models and operate inference services with less waste.
Inference is the process of running a trained model to produce an answer, classification, recommendation, image, or other output. It is often the recurring cost center once an AI feature reaches production. A customer-support assistant, document-processing workflow or consumer-facing generative AI product may serve requests continuously, making utilization, latency and reliability as important as raw model quality.
The practical optimization levers are broad:
- Routing: Directing each request to an appropriate model, region or hardware pool. A relatively simple request may not need the largest available model.
- Scheduling: Assigning work to available GPUs and controlling how requests are queued, batched and retried to reduce idle capacity and prevent overloaded instances.
- Model optimization: Choosing model formats, serving runtimes and numerical precision levels that fit a workload’s accuracy, memory and latency requirements.
- Deployment management: Packaging models, tracking versions, scaling endpoints and maintaining observability across cloud and GPU environments.
- Capacity control: Scaling infrastructure to demand patterns while retaining sufficient headroom for response-time and reliability targets.
These techniques are not interchangeable. More aggressive batching, for example, can raise throughput but may increase the time an individual request waits. Lower-precision execution can reduce memory use and improve performance, but must be validated for model quality. Routing to a smaller model can save money, but a poor router may damage answer quality. The value of an infrastructure platform lies in making such trade-offs measurable and repeatable in a production environment.
Why the 56% claim matters — and its limits
Simplismart’s reported 56% reduction in GPU serving costs for one customer is notable because GPU inference economics can be highly sensitive to deployment configuration. Lowering memory pressure may allow more concurrent requests on a GPU; improving batch formation may increase useful compute per unit of time; and moving the right workloads among hardware pools can reduce the need to provision peak capacity everywhere.
But the result should be treated carefully. Simplismart has not presented it as an independently audited, cross-industry benchmark. The customer is unnamed, and the available report does not establish the customer’s model type, traffic mix, service-level agreements, baseline utilization, cloud pricing, hardware generation or whether the savings included changes beyond the software itself.[1] A workload with initially poor GPU utilization can yield unusually large savings, while a mature deployment may have less optimization headroom.
That distinction matters in a market prone to treating a single customer outcome as a universal percentage. The more useful takeaway is not that every enterprise can halve inference spending. It is that serving costs are often shaped by operational choices that can be improved after the GPU purchase has already been made.
Nvidia’s strategic interest in a more efficient stack
Nvidia’s participation gives Simplismart a strategically important backer because Nvidia sits at the center of the AI-compute market. At first glance, software designed to help companies use fewer GPUs for a given workload could appear to work against a chip supplier’s interests. In practice, efficient deployment can expand the range of AI applications that are economically viable, helping customers put existing infrastructure into production faster and justify future capacity purchases.
That alignment reflects a broader reality of the AI market. Hardware availability remains important, particularly for large model training and high-volume inference. Yet a GPU cluster delivers business value only when it is integrated with reliable software for model serving, networking, monitoring, data movement, scaling and governance. The bottleneck for many organizations is therefore not simply access to compute, but the ability to turn compute into dependable, affordable services.
For Nvidia, an ecosystem of deployment and optimization vendors can strengthen demand for its platforms by reducing friction for enterprises. For Simplismart, Nvidia’s backing may provide commercial credibility in discussions with customers that are weighing cloud, hardware and software choices together. The announcement does not, however, establish preferential access to Nvidia products or guarantee that Simplismart will become a standard layer in Nvidia-based deployments.
A competitive and fragmented AI-infrastructure market
Simplismart enters a crowded category spanning model-serving systems, cloud-management tools, MLOps platforms, inference runtimes and observability products. Hyperscale cloud providers offer managed AI services; GPU cloud operators compete on access and pricing; open-source projects give engineering teams building blocks for serving models; and specialized startups promise better performance, control or portability.
That fragmentation creates an opening for a company that can unify deployment decisions across environments. Enterprises increasingly run mixed estates: some workloads in public clouds, some on dedicated GPU capacity, and some in regional or private infrastructure because of cost, data-residency or latency requirements. Software that provides a common control plane can reduce operational complexity, but it must integrate with customers’ existing identity systems, data pipelines, monitoring tools and security controls.
Simplismart’s claimed 14-fold annualized revenue run-rate growth over six months suggests strong early demand, though run-rate figures are not the same as audited annual revenue and do not by themselves show retention, gross margin or customer concentration.[1] The more durable test will be whether customers continue to pay as AI workloads mature and whether the platform produces repeatable savings across different models, cloud environments and traffic patterns.
The issues customers should examine
Optimization software introduces its own set of technical and commercial questions. Teams should ask how a platform measures cost savings, whether it can distinguish software gains from changes in demand or cloud pricing, and how it protects service-level objectives during traffic spikes. They should also test whether model compression or precision changes affect accuracy, safety behavior and output consistency.
Portability is another concern. A platform that supports multiple clouds and GPU configurations may reduce dependence on a single provider, but its own control plane can become a critical dependency. Customers need clear data-handling terms, audit trails, rollback procedures and a practical exit path. For regulated workloads, deployment automation must also fit security review, access-control and compliance requirements.
The opportunity remains substantial because inference demand is likely to broaden beyond flagship chatbots into specialized business workflows. As models become embedded in software products, operators will need to manage a mix of large and small models, real-time and asynchronous jobs, predictable enterprise demand and volatile consumer traffic. The companies that win may be those that make such complexity less visible to the application team while making cost and performance more visible to finance and operations leaders.
What to watch after the financing
The Series B gives Simplismart capital to pursue product development and customer growth, but the next evidence should be operational. Investors and prospective users will want to see customer deployments beyond a single reported savings case, retention data, workload-specific performance results and proof that savings survive changes in models and cloud pricing.
The larger trend is clear: AI infrastructure is becoming an efficiency contest as much as a procurement contest. The most valuable deployment software will not merely display GPU utilization dashboards. It will make defensible, automated decisions about models, hardware, latency and cost while preserving quality and reliability. Simplismart’s funding is one indication that investors see that control layer as a meaningful part of the AI stack.
Editor’s Take
I view this as a healthy sign that the market is moving past a simplistic race to accumulate GPUs. Buying accelerators is necessary for many AI products, but operating them efficiently is where a large share of the recurring economics is decided. A tool that can safely raise utilization, select an appropriately sized model and reduce waste in serving can be more valuable to an enterprise than another isolated benchmark gain.
The 56% figure deserves skepticism until it is reproduced across named, well-described workloads. Still, the claim is directionally credible because many production deployments remain overprovisioned or poorly tuned. What I would watch next is whether Simplismart can publish consistent outcomes while preserving latency and model quality—and whether it can do so across the messy mix of clouds, models and compliance constraints that real customers actually run.